AI Observability and Evaluation Operations System PRD Template
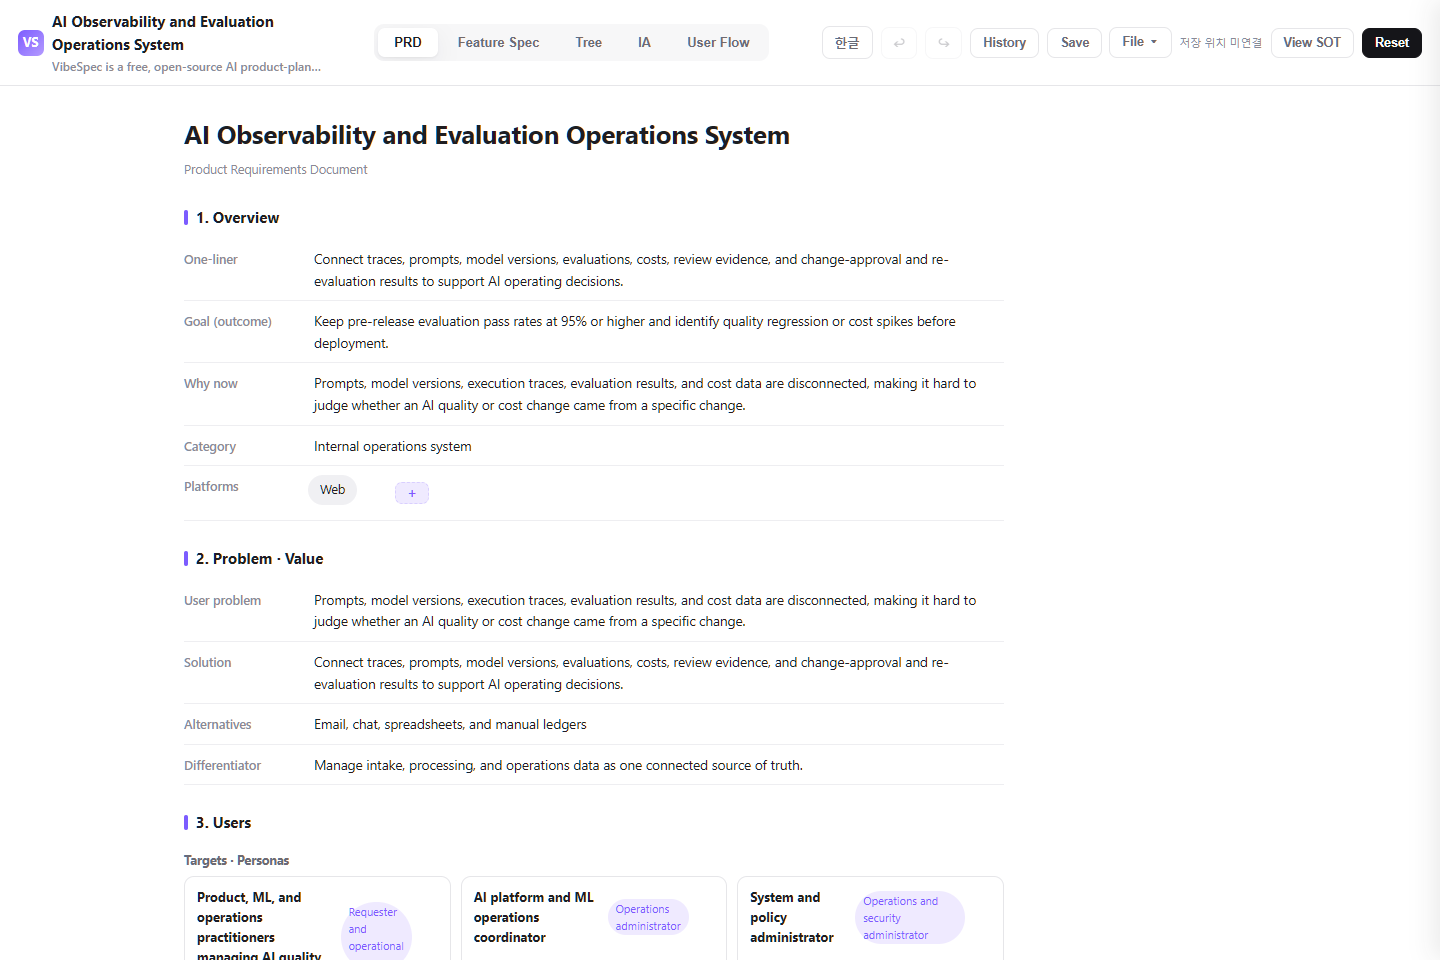
A SOT-based PRD template for planning AI observability and evaluation operations, covering traces, prompt and model versions, evaluation sets, quality and safety reviews, token costs, change approvals, and re-evaluation.
Teams planning an internal AI operations system for product, ML, and operations practitioners who manage AI quality, cost, and safety, plus AI platform and MLOps teams.
CONTENTS
What the template includes
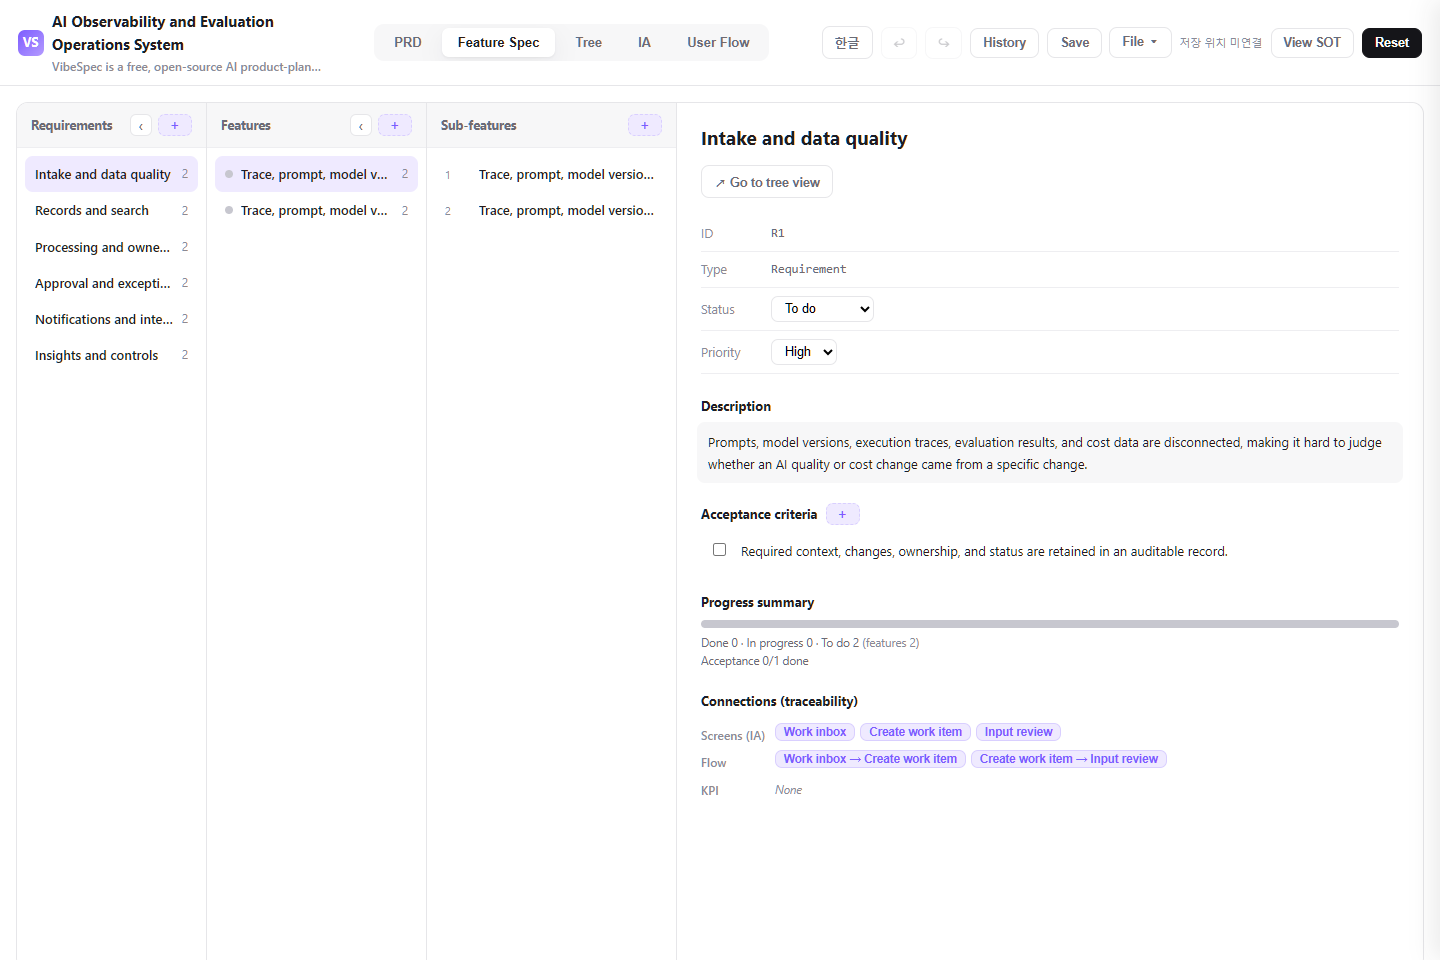
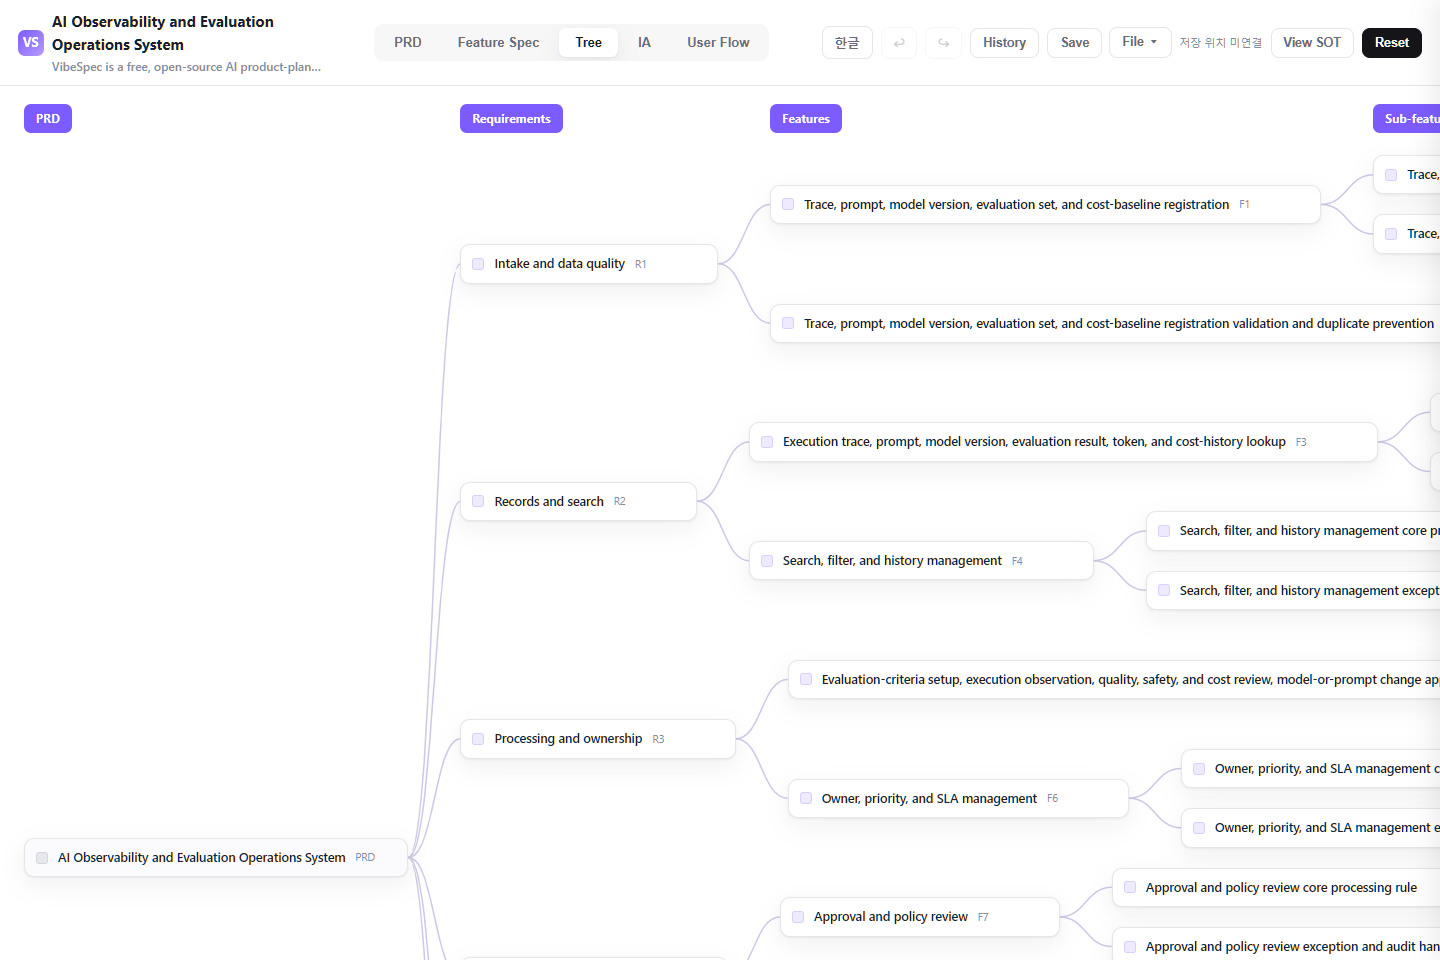
Trace, prompt, model version, evaluation set, and cost-baseline registration
Execution trace, prompt, model version, evaluation result, token, and cost-history lookup
Evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling
How to use and adapt this AI Observability and Evaluation Operations System
This plan gives product, ML, and AI platform operators one evidence trail for model and prompt changes. It connects traces, prompt and model versions, evaluation sets, quality and safety results, token costs, and the approval record for each release candidate. Teams can decide whether to approve, hold, or re-evaluate a change without losing the run history behind that decision. Review the HTML, then adapt the SOT JSON in Claude or Codex with the VibeSpec plugin.
What this AI Observability and Evaluation Operations System actually includes
Trace, prompt, model version, evaluation set, and cost-baseline registration
For trace, prompt, model version, evaluation set, and cost-baseline registration, define the required context, classification rules, and duplicate or missing-data checks before work enters the operating queue.
Execution trace, prompt, model version, evaluation result, token, and cost-history lookup
For execution trace, prompt, model version, evaluation result, token, and cost-history lookup, keep status, owner, priority, and change history together so the team can find the complete operating context.
Evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling
In evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling, connect assignment, approval or rejection, exception handling, and completion confirmation as one accountable workflow.
Use response quality, evaluation pass rate, safety violation, latency, token usage, and model-cost reporting to track due dates, bottlenecks, exceptions, and completion outcomes by team, period, and operating category.
Policy, access, and integration foundations
Set the role-based access, audit history, notifications, and external-system boundaries that AI Observability and Evaluation Operations System needs to operate safely.
Start in three steps, even without planning experience
1. Review the complete HTML with your team
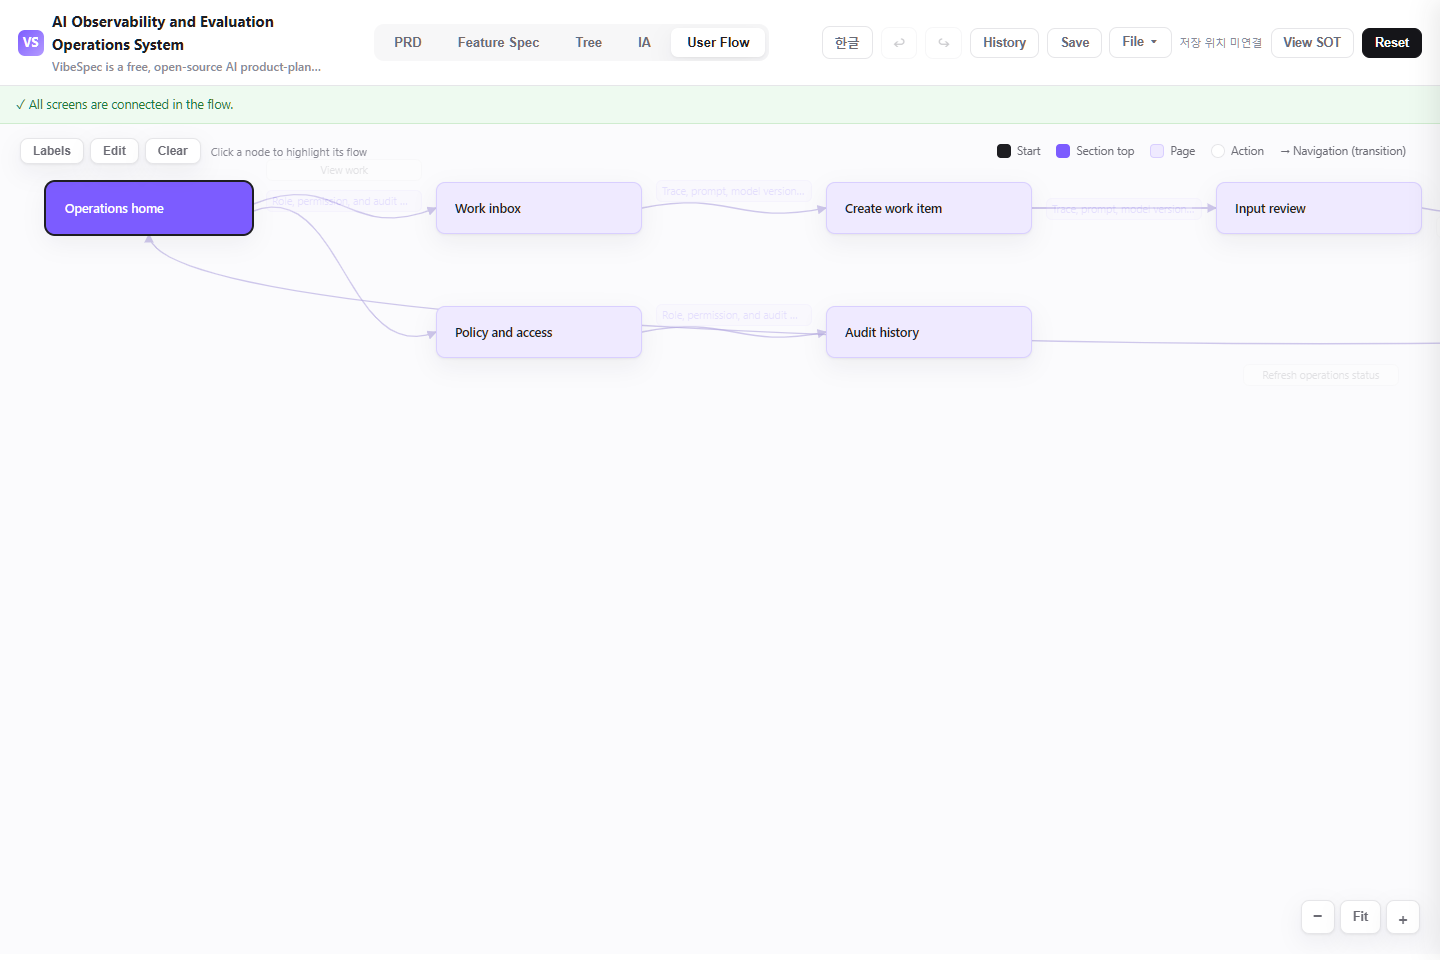
The download opens in a browser without setup. Compare the PRD, feature specification, screen structure, and user flow with the work your team does today.
2. Name your operating rules
Write down real user roles, required data, approval rules, exceptions, and success metrics. Start with the core flow from trace, prompt, model version, evaluation set, and cost-baseline registration through evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling.
3. Give the SOT JSON to VibeSpec
Attach the SOT JSON in Claude or Codex with the VibeSpec plugin and describe the change in plain language. VibeSpec keeps requirements, features, screens, and user flows connected.
Adapt this AI Observability and Evaluation Operations System for your team
Rename terms and states first
Replace the template vocabulary, states, and classification with the terms your team uses. Keep trace, prompt, model version, evaluation set, and cost-baseline registration and execution trace, prompt, model version, evaluation result, token, and cost-history lookup consistent.
Make roles, approvals, and exceptions explicit
Define who registers, reviews, approves, processes, and confirms completion, plus the conditions that trigger rejection or reprocessing in evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling.
Keep screens, metrics, and integrations connected
Decide what response quality, evaluation pass rate, safety violation, latency, token usage, and model-cost reporting should measure, then connect any SSO, messaging, or adjacent-system integration to the related screens and user flow.
Capabilities to add next
Trace and evaluation ingestion
Add OpenTelemetry traces, evaluation runners, and model-gateway feeds with explicit prompt-version, latency, token, cost, result, duplicate-run, and ingestion-failure handling.
Deployment gates
Connect CI/CD or model deployment tools to approved evaluation sets and cost baselines, then return pass, hold, and exception-approval outcomes to the governed change record.
Regression and cost-drift analysis
Compare quality, safety, latency, and unit-cost baselines by model, prompt, and evaluation set, with explicit thresholds that trigger re-evaluation or rollback review.
Prompts you can use with VibeSpec
Adapt it to our terminology and roles
Adapt this AI Observability and Evaluation Operations System for our team. Ask about our user roles, states, required fields, and approval steps first, then update the requirements, screens, and user flows together.
Simplify it into an MVP
Reduce this AI Observability and Evaluation Operations System to an MVP that keeps trace, prompt, model version, evaluation set, and cost-baseline registration, execution trace, prompt, model version, evaluation result, token, and cost-history lookup, and evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling. Move automation and external integrations into separate initiatives.
Resolve a KPI Measurement Check decision
Use KPI Measurement Check as a measurement-readiness review for the pre-release evaluation pass rate. Identify unresolved evaluation-set versioning, pass criteria, denominator, and release-change linkage. Ask for owners and decisions first, then produce a scoped change plan limited to affected requirements, feature specs, screens, user flows, and measurement events.
AI Observability and Evaluation Operations System FAQ
Can I use this template without development experience?
Yes. The complete HTML opens in a browser for review and sharing. To adapt the plan, attach the SOT JSON to Claude or Codex with the VibeSpec plugin and describe the change in plain language.
What is included in this planning template?
It includes trace, prompt, model version, evaluation set, and cost-baseline registration, execution trace, prompt, model version, evaluation result, token, and cost-history lookup, evaluation-criteria setup, execution observation, quality, safety, and cost review, model-or-prompt change approval, and re-evaluation handling, and response quality, evaluation pass rate, safety violation, latency, token usage, and model-cost reporting, plus foundations for access, audit history, notifications, and integrations.
What is the difference between the HTML and SOT JSON downloads?
The HTML is a complete planning document for reading and sharing. The SOT JSON is source data that VibeSpec can update while keeping requirements, features, screens, and user flows connected.
Does KPI Measurement Check automatically assure AI quality?
No. KPI Measurement Check is a measurement-readiness review for whether a KPI such as evaluation pass rate can be computed from defined product functions and data. It does not automatically assure model quality or safety.
WORKFLOW
Use it with VibeSpec
Open the complete HTML file to review or share it immediately.
Download the SOT JSON and load it in the VibeSpec viewer.
Adapt the features, screens, and flows for your team.